Resgrid on Kubernetes / k3s
The multi branch of resgrid-setup deploys Resgrid to a Kubernetes cluster spread over several servers. It is the production-grade layout: the stateless Resgrid services can run several replicas, nodes can be drained for maintenance without downtime, and the stateful services keep their data on persistent volumes. It needs only kubectl (its built-in Kustomize) and works out of the box on k3s and on any conformant cluster (kubeadm, RKE2, AKS, EKS, GKE).
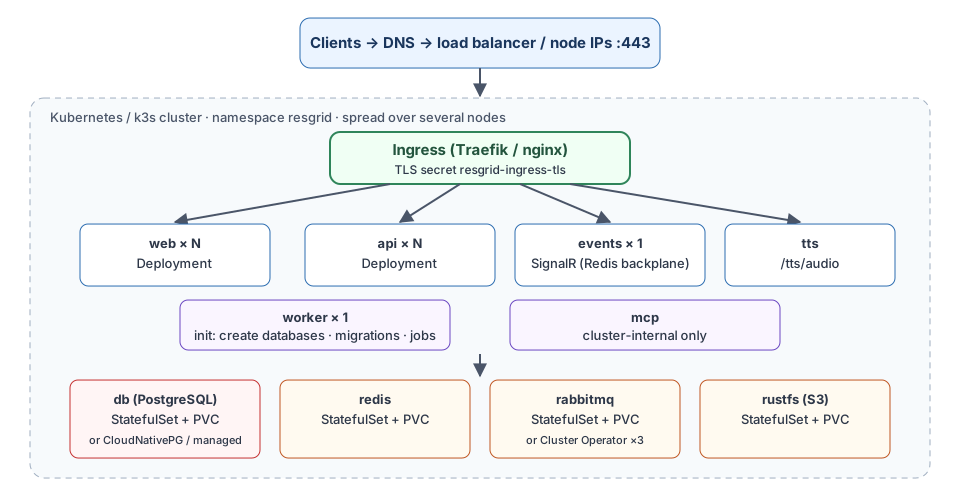
| Kind | Name | Notes |
|---|---|---|
| Deployment | web, api | Stateless; scale freely. Session keys and the real-time backplane live in Redis. |
| Deployment | events | One replica unless your ingress supports sticky sessions (real-time clients negotiate and connect in two requests). |
| Deployment | worker | Exactly one. Its init container creates the four databases; the worker then creates/migrates the schema and runs scheduled jobs. |
| Deployment | tts, mcp | Text-to-speech; MCP for AI assistants (cluster-internal only, its endpoint is unauthenticated). |
| StatefulSet | db, redis, rabbitmq, rustfs | One replica each with a ReadWriteOnce volume (20, 2, 5, 20 GiB). |
| Job | rustfs-init | Creates the object storage buckets. |
| Ingress | resgrid | Web, API (plus /tts/audio) and events hostnames with TLS. |
Every Resgrid pod runs as non-root on port 8080, has readiness probes, resource requests and limits, and trusts the Resgrid local CA (ConfigMap resgrid-ca).
Requirements
- Kubernetes 1.27+ or k3s with at least one
linux/amd64node (the published Resgrid images are amd64-only today). - A default
ReadWriteOnceStorageClass (k3s:local-path) and an IngressClass (k3s:traefik). - A workstation with
kubectlconnected to the cluster,opensslandbash(Linux, macOS or WSL). - DNS records for the web, API and events hostnames pointing at the ingress address (the k3s nodes, or your load balancer).
- Capacity: the base install requests about 2 vCPU and 3 GB of RAM. Three nodes with 4 vCPU / 8 GB each is a good production start.
Step 1: Build the cluster (k3s)
Skip this if you already have a cluster. On the first server:
curl -sfL https://get.k3s.io | sh -s - server --cluster-init
sudo cat /var/lib/rancher/k3s/server/node-token
On two more servers, for a highly available control plane with embedded etcd:
curl -sfL https://get.k3s.io | K3S_URL=https://<first server>:6443 K3S_TOKEN=<token> sh -s - server
Copy /etc/rancher/k3s/k3s.yaml from the first server to your workstation as ~/.kube/config, replace 127.0.0.1 in it with the first server's address, and check:
kubectl get nodes -o wide
kubectl get storageclass,ingressclass
Step 2: Configure and deploy
git clone --branch multi https://github.com/Resgrid/resgrid-setup.git resgrid-k8s
cd resgrid-k8s
./setup.sh
setup.sh asks for the three hostnames, the IngressClass (traefik on k3s) and the pod network (10.42.0.0/16 on k3s), then:
- Writes
deploy/generated/resgrid.envwith every password, key and the OpenID Connect certificates. - Creates the Resgrid local CA and issues the ingress certificate for the three hostnames from it, unless you pass your own certificate with
RESGRID_TLS_CERT_FILE/RESGRID_TLS_KEY_FILE(recommended for production). - Finds the ingress controller's cluster address and lets the pods reach the public hostnames through it (the web app gets API tokens from the API's public URL; events and MCP call it too).
- Shows the
kubectlcontext, asks you to typeyes(once per context), applies everything and waits for the rollout. - Walks you through the optional features (Records, Unified search, Chat, Run cards, virus scanning, ...), one question per feature (Optional features and upgrades):
==> Pods will reach the public hostnames through the ingress at 10.43.110.230.
==> Validating manifests
Apply Resgrid to Kubernetes context 'default'? Type yes [no]: yes
==> Applying to context default
...
==> Waiting for the database migration and the web app (first install: 5-15 minutes)
deployment "worker" successfully rolled out
deployment "api" successfully rolled out
deployment "web" successfully rolled out
deployment "events" successfully rolled out
Watch the first start:
kubectl -n resgrid get pods -w
kubectl -n resgrid logs -f deployment/worker
Unattended:
RESGRID_WEB_HOST=dispatch.example.com RESGRID_API_HOST=dispatchapi.example.com \
RESGRID_EVENTS_HOST=dispatchevents.example.com RESGRID_INGRESS_CLASS=traefik \
RESGRID_POD_CIDR=10.42.0.0/16 RESGRID_TLS_CERT_FILE=/secure/fullchain.pem \
RESGRID_TLS_KEY_FILE=/secure/privkey.pem RESGRID_FEATURES=records,search RESGRID_APPLY=1 ./setup.sh
RESGRID_NO_APPLY=1 ./setup.sh only writes the files; inspect the result with kubectl kustomize deploy.
deploy/generated/ holds every secret and the CA key. Back it up securely; it is not in git.
Step 3: Create your department
Open https://<web hostname>, choose Create an account and register your department. Then turn self-service sign-up off: set RESGRID__SystemBehaviorConfig__AllowSignupWithoutBilling=false in deploy/generated/resgrid.env and run ./setup.sh.
With the local CA, install deploy/generated/ca.crt on client devices (Certificates). Android phones running the Resgrid apps need a publicly trusted certificate.
Images and pull limits
Pods pull resgridllc/*:latest (imagePullPolicy: Always, so a restart picks up new releases) and hardened infrastructure images from dhi.io. Docker Hub limits anonymous pulls; give the namespace credentials:
kubectl -n resgrid create secret docker-registry regcred --docker-server=https://index.docker.io/v1/ --docker-username=<user> --docker-password=<token>
kubectl -n resgrid create secret docker-registry dhi --docker-server=dhi.io --docker-username=<user> --docker-password=<token>
kubectl -n resgrid patch serviceaccount default -p '{"imagePullSecrets":[{"name":"regcred"},{"name":"dhi"}]}'
For change control in production, pin versions with an images: block in deploy/kustomization.yaml.
Operations
kubectl -n resgrid get pods,pvc,ingress
kubectl -n resgrid logs -f deployment/api
kubectl -n resgrid scale deployment/web deployment/api --replicas=3
Change settings in deploy/generated/resgrid.env, then run ./setup.sh (re-applies the Secret and restarts the deployments).
Optional features: ./setup.sh features turns Records, Unified search, Chat, Run cards, virus scanning and the other optional modules on or off (Optional features and upgrades). Flags are switched through kubectl exec into db-0; virus scanning applies deploy/optional/clamav.yaml.
Upgrade and repair: ./setup.sh upgrade (git pull, then the same as ./setup.sh). Re-running setup is always safe: it adds new settings and repairs broken ones in resgrid.env, recreates missing generated files, re-applies the manifests (the bucket job runs again, so new buckets exist), restarts StatefulSet pods stuck on an older definition, restarts the deployments so they pull the latest images (the worker migrates the database) and asks only about new optional features. It never replaces a value you set or deletes data. Back up first.
Backup:
day=$(date +%F)
kubectl -n resgrid exec statefulset/db -- sh -c 'pg_dumpall -U "$POSTGRES_USER" --clean --if-exists' > resgrid-$day.sql \
  && gzip -f resgrid-$day.sql
Compress only after pg_dumpall succeeds (as above) or run the pipeline under set -o pipefail: pg_dumpall | gzip returns gzip's status, so a failed kubectl exec or dump otherwise leaves a .sql.gz that looks valid and is empty or truncated.
Also keep deploy/generated/ and snapshots of the data-rustfs-0 volume.
Restore (database):
day=2026-10-27                     # the date of the backup you are restoring
kubectl -n resgrid get deploy -o jsonpath='{range .items[*]}{.metadata.name}{" "}{.spec.replicas}{"\n"}{end}' > replicas-$day.txt
kubectl -n resgrid scale deployment --all --replicas=0
kubectl -n resgrid wait --for=delete pod -l 'app notin (db,redis,rabbitmq,rustfs)' --timeout=5m
gunzip -c resgrid-$day.sql.gz | kubectl -n resgrid exec -i statefulset/db -- sh -c 'psql -q -U "$POSTGRES_USER" -d postgres'
while read -r name replicas; do kubectl -n resgrid scale deployment "$name" --replicas="$replicas"; done < replicas-$day.txt
kubectl scale only changes the desired replica count; the pods terminate afterward. Wait for the API, events and worker pods to be gone (the wait above, or kubectl -n resgrid get pods until only the StatefulSet pods are left) before loading the dump, or they write to the database while it is being replaced. Adjust the label selector to the labels your manifests set.
Record the replica counts first and replay them (the replicas-$day.txt round trip above) rather than scaling a fixed list back to 1: --all stops the optional Deployments too, and a hard-coded --replicas=1 would also undo scaling such as three web and api replicas.
This replays the database only. For a full recovery also restore the data-rustfs-0 snapshot from the same backup, with your cluster's snapshot or CSI tooling, while the rustfs StatefulSet is scaled to 0 — database rows point at the TTS audio and import objects in it, so a database-only restore leaves records referencing objects that no longer exist. The Unified search index needs no backup: the worker rebuilds it.
Certificate renewal (local CA): ./setup.sh renew-cert re-issues the ingress certificate (valid 397 days).
Production hardening
The base keeps one replica of each stateful service so it runs on any cluster. For high availability:
- PostgreSQL: CloudNativePG or a managed database with replicas and scheduled backups. Point the five
*ConnectionStringsettings at it and remove thedbStatefulSet. - RabbitMQ: the RabbitMQ Cluster Operator with three nodes (
RabbitHostname,RabbitHostname2,RabbitHostname3); keepdeprecated_features.permit.transient_nonexcl_queues = truein its configuration. - Redis: a managed Redis or Sentinel.
- Object storage: RustFS in distributed mode or any S3 service.
- Spread
webandapireplicas over nodes, add PodDisruptionBudgets, and use replicated storage (Longhorn, Ceph, cloud volumes).
Optional services
Optional services are the files in deploy/optional/ listed in RESGRID_OPTIONAL (comma separated) in deploy/generated/resgrid.env; ./setup.sh applies them on every run and removes the ones it applied before that you took off the list. clamav is managed by the virus-scanning feature. For GPS trackers or inbound email dispatch, enable their settings, add tracking or relay to RESGRID_OPTIONAL and run ./setup.sh. Both create LoadBalancer services. The relay needs its department (RESGRID__RELAY__Resgrid__DepartmentId) and dispatch domains (RESGRID__RELAY__Smtp__DepartmentAddressDomains__0) set, and the domains' MX records pointed at the service: it only accepts recipients in those domains. It is not an open mail relay, but it accepts any sender and offers no TLS or SMTP authentication, so restrict port 25 to the senders you expect or put a filtering MTA that terminates TLS in front of it before exposing it to the internet.
Troubleshooting
| Symptom | Fix |
|---|---|
Pods stuck in ErrImagePull with 429 Too Many Requests | Docker Hub rate limit: add pull credentials (above). |
No amd64 node found | Add an amd64 node; the Resgrid images are amd64-only today. |
| Web loads but login or live updates fail | The API or events hostname doesn't resolve or isn't trusted on the client. Inside the cluster, check kubectl -n resgrid get pod -l app=web -o jsonpath='{.items[0].spec.hostAliases}'. |
| Worker init container fails | PostgreSQL isn't ready yet; it retries. Check kubectl -n resgrid logs deploy/worker -c create-databases. |
kubectl delete -k deploy deleted the data | Most storage classes delete volumes with the namespace. Restore from backup. |